
Q: 32
DRAG DROP You design a project for interactive data mangling with Apache Spark in an Azure Machine Learning workspace. The data pipeline must provide the following solution: • Ingest and process a vast amount of data from various sources and linked services, such as databases and APIs • Visualize the results in Microsoft Power Bl. • Include a possibility to quickly identify and address issues by observing only a small amount of data using the fewest resources. You need to select a computation option for project activities. 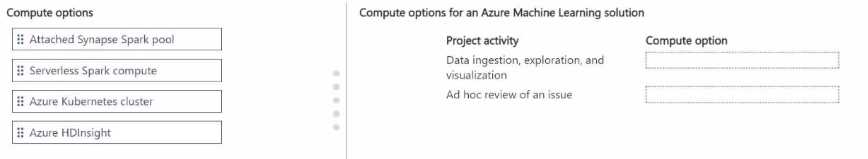
Drag & Drop
Discussion
No comments yet. Be the first to comment.
Be respectful. No spam.