
Q: 16
HOTSPOT You plan to use Hyperdrive to optimize the hyperparameters selected when training a model. You create the following code to define options for the hyperparameter experiment 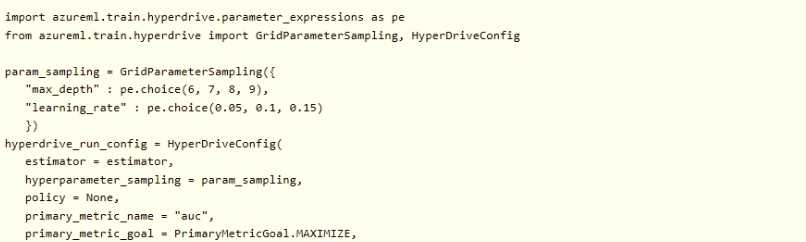
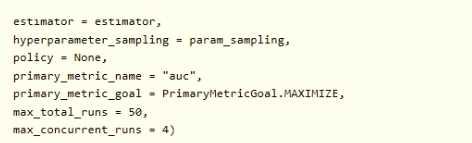 For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
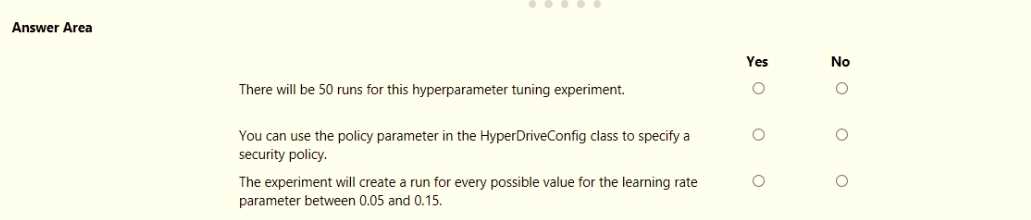
Your Answer
Discussion
Update Import Data → Run pipeline → Register dataset → Deploy model. Saw a similar question before and this order avoids the trap of registering before running the pipeline. Makes sense since you want new data first, right? Correct me if I missed something.
Update Import Data → Run pipeline → Register dataset → Deploy model
Update Import Data -> Run pipeline -> Register dataset -> Deploy model. That's my guess. Makes sense to prep the new data first before running and then registering and deploying, but not 100% sure on the last two steps swapping places. Anyone disagree?
Update Import Data for new files, then run pipeline, after that register new dataset and deploy updated model. Pretty sure that’s it.
Had something like this in a mock. I think you first update the Import Data module to point to the new files, then run the pipeline, register the new dataset, and finally deploy the updated model. Let me know if that's off.
Be respectful. No spam.