HOTSPOT You plan to deploy an Azure OpenAI resource by using an Azure Resource Manager (ARM) template. You need to ensure that the resource can respond to 600 requests per minute. How should you complete the template? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point. 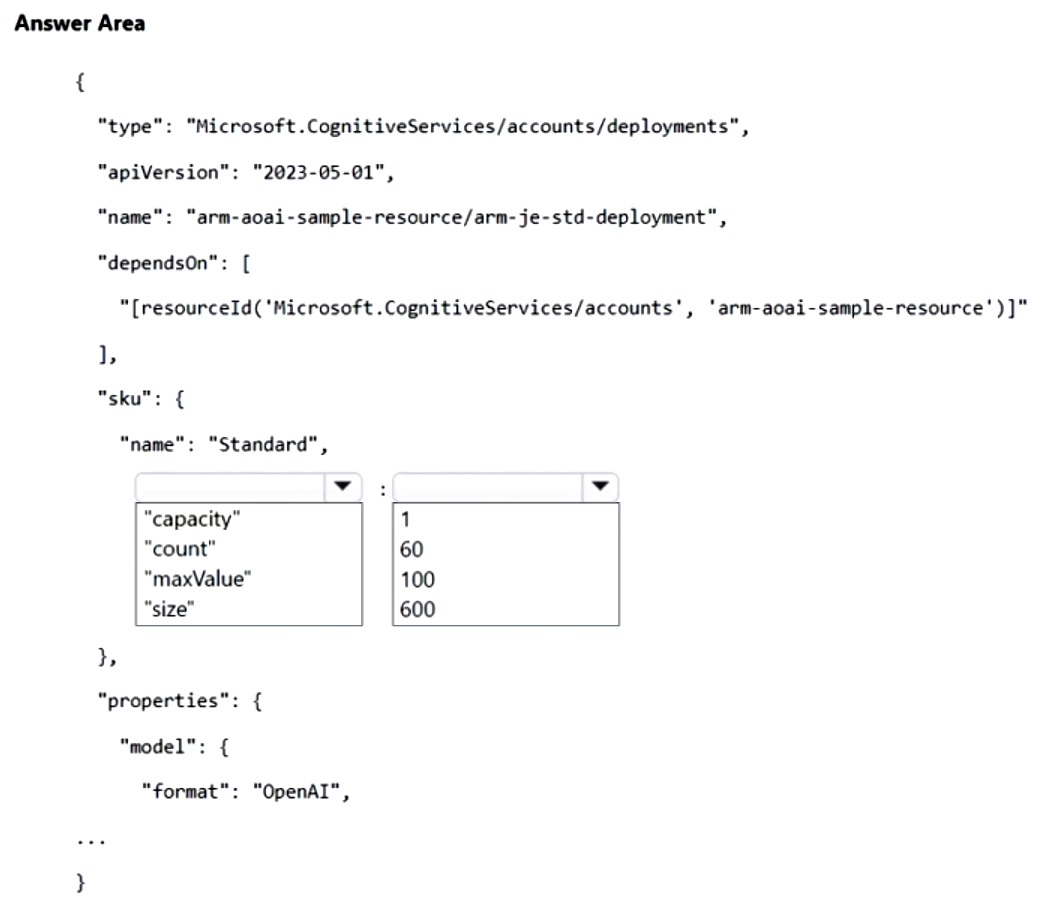
Isn’t the capacity property in ARM templates what actually controls throughput for Azure OpenAI, not maxRequestsPerMinute? The question wants 600 RPM consistently, so setting capacity to 100 makes sense if you follow the token/request ratio. Am I missing a detail here, or is there a trap about request versus token limits?
Shouldn’t the first box be maxRequestsPerMinute? The ARM template docs mention that property for rate limiting, not capacity.
Just to be clear, are they asking for the best way to ensure sustained 600 requests per minute, or just a one-time burst? The required capacity setting changes if they mean burst vs. continuous load.